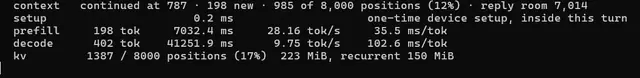
u/TypicalPudding6190@TypicalPudding6190 · Sep 27A team built an engine that keeps most of the NVFP4 model on SSD and reads experts as tokens need them, reaching 9-10 tok/s decode on a 16GB card with 32GB RAM.