VRAM benchmark across Flash-Next configurations
 lukaLLM
Community measurements of memory needs at different quants and contexts.
- Launch
- Qwen3.8-Flash-Next
- Use case
- Benchmarks
- Format
- Repo
- Source
- github.com
lukaLLM
Community measurements of memory needs at different quants and contexts.
lukaLLM

0xSero
@0xSero · Sep 29
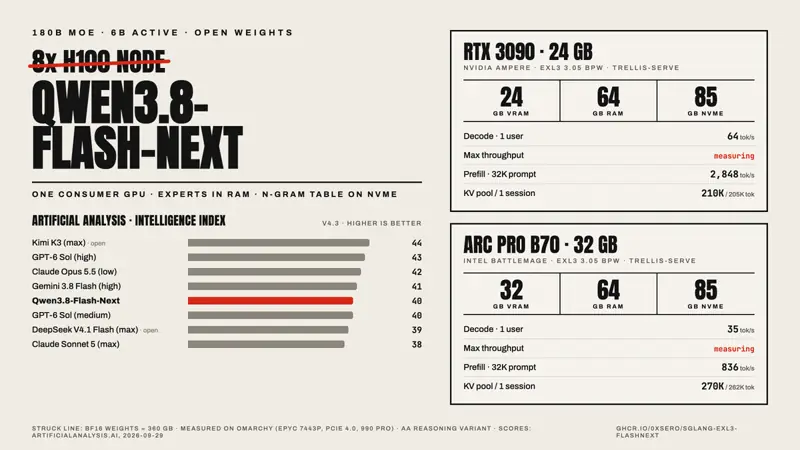
Reports prefill and decode speeds for a single 24-32GB GPU plus NVMe, including an Intel Arc B70 result.

Niko1221
@Niko1221 · Sep 24
Open-source inference engine with an OpenAI/Anthropic-style local API that fits the 125B MoE onto a 12GB consumer GPU plus system RAM. The project behind the model's local-running surge.