Comparison
GPT-6.1 Sol vs Qwen3.8-Flash-Next
People have published 44 builds with GPT-6.1 Sol and 139 with Qwen3.8-Flash-Next, overlapping in 5 use cases. GPT-6.1 Sol has more coding, games, agents examples.
GPT-6.1 Sol
Successor to GPT-6 Sol, announced at OpenAI DevDay on 2026-09-29 with near-Astra intelligence for a fifth of the price: $2 input and $10 output per million tokens, a 1.05M-token context window and five reasoning levels. Rolled out in ChatGPT Work, Codex and the API.
- 44
- Entries
- 42
- Creators
- GitHub, YouTube, X
- Top source
Qwen3.8-Flash-Next
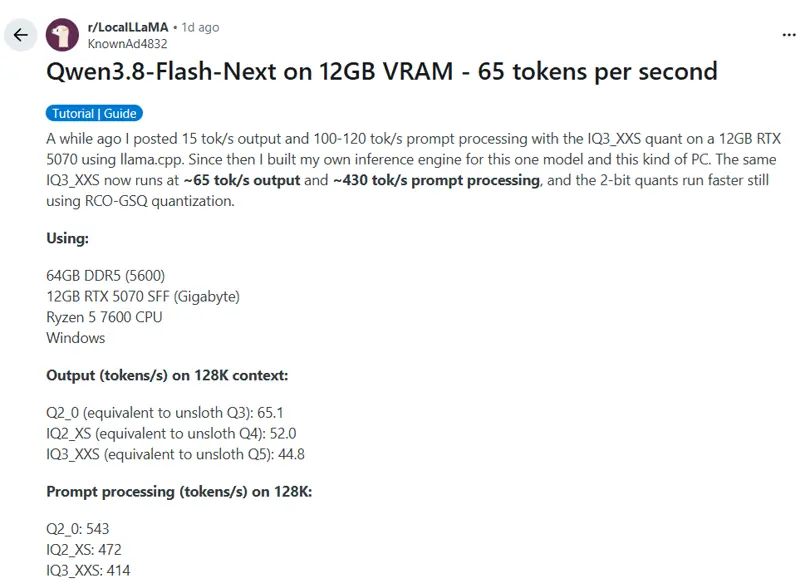
Open-weight 125B-parameter multimodal MoE (about 6B active, plus a 51B n-gram embedding table) from Alibaba's Qwen team, an early preview of the Qwen4 architecture. Its n-gram table can sit in system RAM or on SSD, which let community engines such as Strata run it on gaming PCs and Macs.
- 139
- Entries
- 131
- Creators
- GitHub, Reddit, X
- Top source
Same use case, side by side
Use caseGPT-6.1 SolQwen3.8-Flash-Next
Coding
Qwen3.8-Flash-Next · 4 entriesGVS5H: five Qwen3.8 models matching a frontier model on LiveCodeBench Hard
Games
Agents
Design
Education
Top builds with GPT-6.1 Sol
- 1GPT-6.1 Sol Is So Weirdon YouTube:Can It Code?· 94.3K views
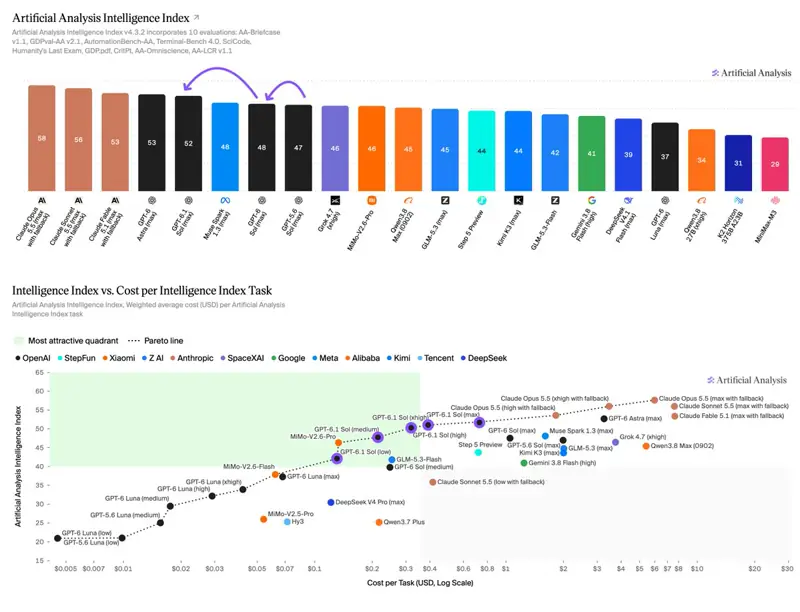
- 2Artificial Analysis on X: Sol replaces GPT-6 Sol after seven dayson X:Artificial Analysis· 2K likes
- 3GPT 6.1 Sol or Opus 5.5? One Got Gappedon YouTube:Can It Code?· 41.7K views
- 4I Tested NEW GPT-6.1 Sol on Coding. I'm Shocked.on YouTube:AI Coding Daily· 27.1K views
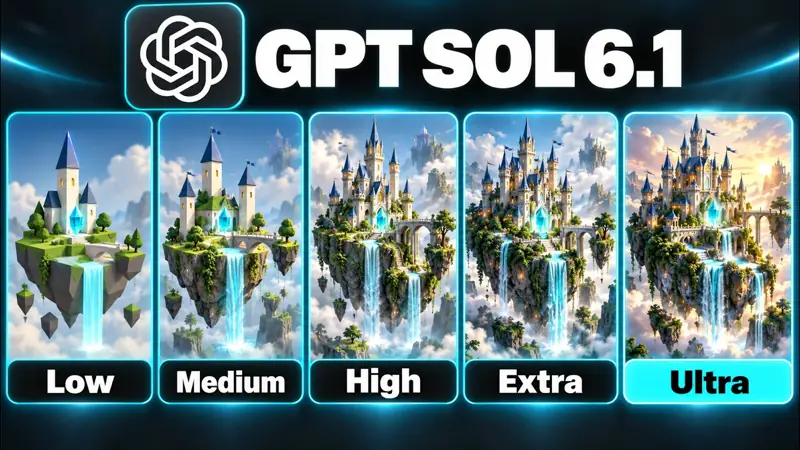
- 5GPT-6.1 Sol builds the same 3D scene at every effort levelon YouTube:Code Bear· 24.6K views
Top builds with Qwen3.8-Flash-Next
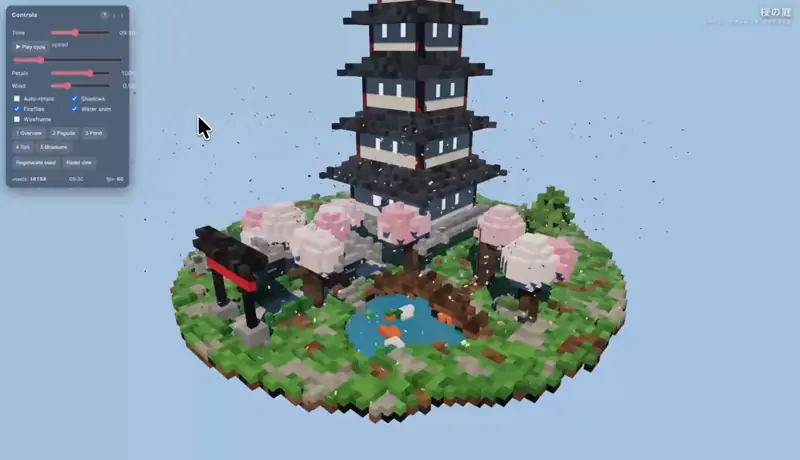
- 1Strata: one-click engine for running the 125B Flash-Next on a gaming PCon GitHub:Niko1221· 16.8K stars
- 2Flash-Next on a single DGX Spark (TP=1)on GitHub:MiaAI-Lab· 594 stars
- 3Halogen: fastest Flash-Next server for AMD Strix Haloon GitHub:peonist-ai· 876 stars
- 4GVS5H: five Qwen3.8 models matching a frontier model on LiveCodeBench Hardon GitHub:slee-persis· 736 stars
- 5From 15 tps on llama.cpp to 65 tps with a home-built engineon X:David Hendrickson· 1.6K likes