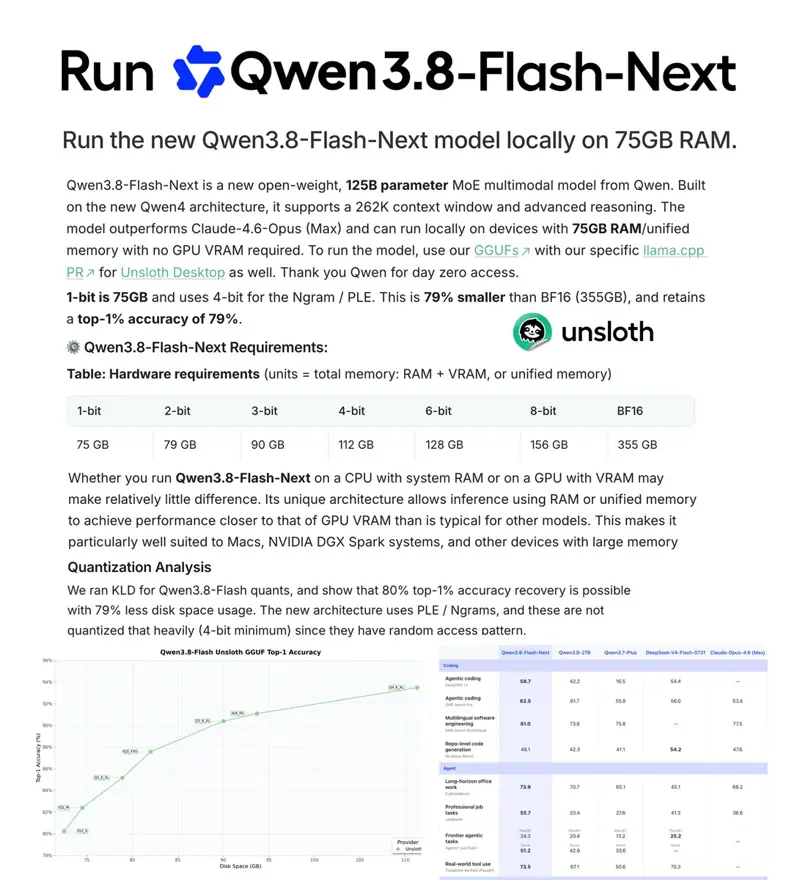
From 15 tps on llama.cpp to 65 tps with a home-built engine
 David Hendrickson
- Launch
- Qwen3.8-Flash-Next
- Use case
- Local inference
- Format
- Post
- Source
- x.com
David Hendrickson
CEO & Founder | PhD | Startup Advisor | @Columbia | Author Generative Software Engineering https://tinyurl.com/7ymyv4sb | 🔔 Follow for AI & Vibe Coding Tips 👇