Unsloth GGUFs: run Flash-Next on 75GB RAM
 Unsloth AI
- Launch
- Qwen3.8-Flash-Next
- Use case
- Local inference
- Format
- Post
- Source
- x.com
Unsloth AI
Run and train models locally with the Unsloth Desktop app. 🦥 https://github.com/unslothai/unsloth
Unsloth AI
Run and train models locally with the Unsloth Desktop app. 🦥 https://github.com/unslothai/unsloth

Niko1221
@Niko1221 · Sep 24
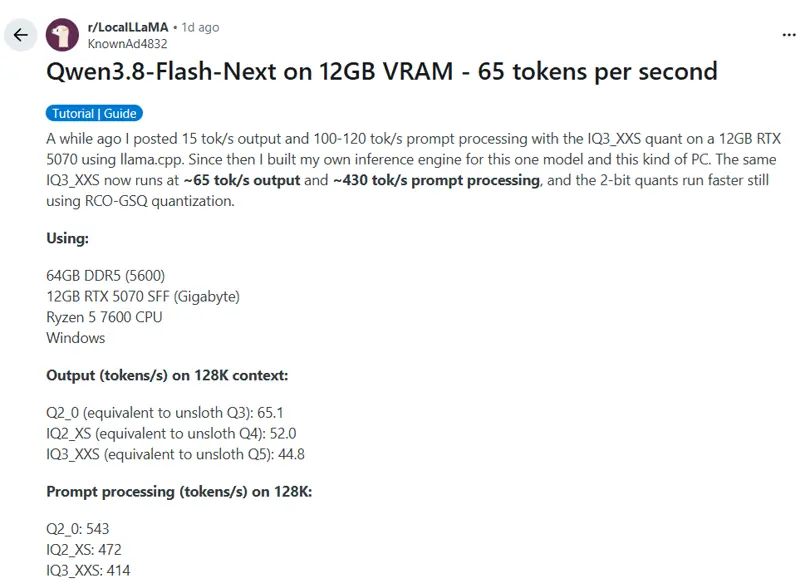
Open-source inference engine with an OpenAI/Anthropic-style local API that fits the 125B MoE onto a 12GB consumer GPU plus system RAM. The project behind the model's local-running surge.

David Hendrickson
@TeksEdge · Sep 26
Tells the story of the 12GB RTX 5070 user who wrote Strata after finding llama.cpp too slow.