exllamav3-amd: WMMA GEMV port gives 41 tok/s on Strix Halo
 Victor Cruz
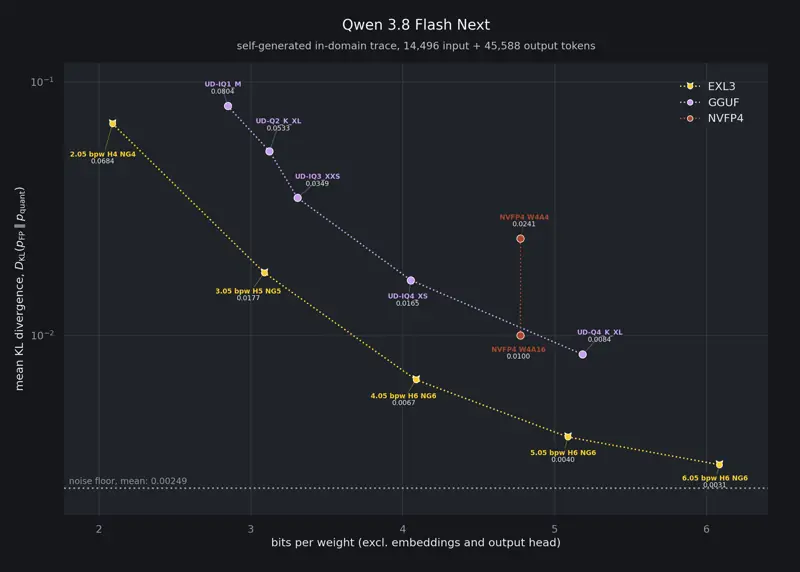
Ports ExLlamaV3 kernels to RDNA 3.5 with grouped MoE, int8 mixers and MTP. The author quantizes frontier models down to fit smaller GPUs.
- Launch
- Qwen3.8-Flash-Next
- Use case
- Amd local
- Format
- Repo
- Source
- github.com
Victor Cruz
I quantize frontier models down into EXL3 and GGUF to fit on smaller GPUs, while also creating the most optimal recipes