peonist-ai
@peonist-ai · Aug 26
Container-based server tuned for the gfx1151 Strix Halo APU, aimed at squeezing maximum tokens per second from the 125B model on a mini-PC.
Alibaba Cloud· Released Aug 26
peonist-ai
@peonist-ai · Aug 26
Container-based server tuned for the gfx1151 Strix Halo APU, aimed at squeezing maximum tokens per second from the 125B model on a mini-PC.

IIIIIllllIIIIIlllll
@IIIIIllllIIIIIlllll · Sep 19
An inference engine written for Ryzen AI MAX 395 on Linux and Windows that deploys only Qwen-family MoE models. The author is an automation engineer, not a full-time programmer, who built it to get more out of his mini PC.

shawnshekari
@shawnshekari · Oct 4
An LLM engine written from scratch in HIP for AMD Strix Halo and Qwen3.8-Flash-Next, reaching about 50 tokens per second out. Built to see how far a single-model engine can go.

Aristo94
@Aristo94 · Oct 2
A llama.cpp fork that speeds ROCm prefill and fits multi-token prediction for GSQ quantizations on AMD gfx1151 hardware.

vcruz305
@vcruz305 · Sep 17
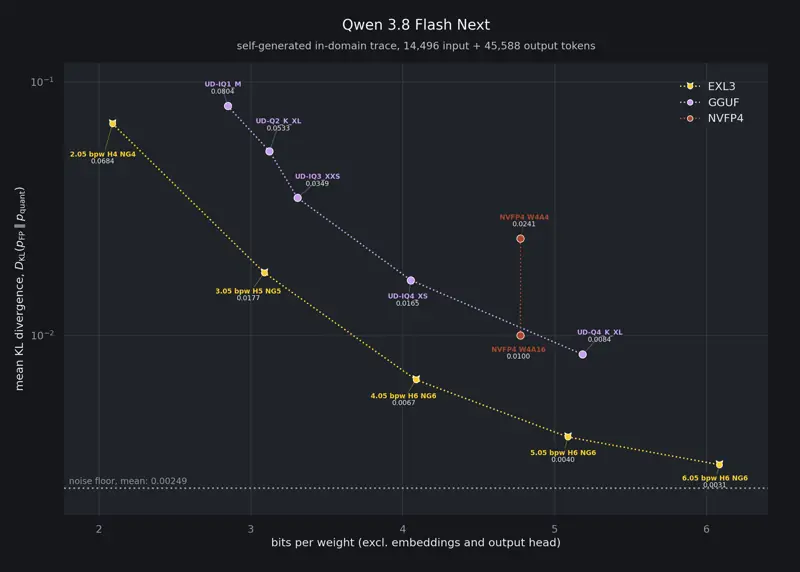
Ports ExLlamaV3 kernels to RDNA 3.5 with grouped MoE, int8 mixers and MTP. The author quantizes frontier models down to fit smaller GPUs.

drluoto
@drluoto · Aug 29
Draft-head speculation and carefully measured Vulkan settings that lift Flash-Next speed on Strix Halo. Notable for publishing the measurement method as well as the numbers.

abliter8-ai
@abliter8-ai · Aug 28
A step-by-step serving recipe for running the 125B MoE on one Ryzen AI MAX+ 395 box, written by a hobbyist. Useful as a replicable baseline for that hardware.

olliehm
@olliehm · Sep 10
Build recipe, Lemonade deployment, an admission shim and benchmarks for Windows users, a platform most community recipes skip.

u/KnownAd4832
@KnownAd4832 · Oct 6
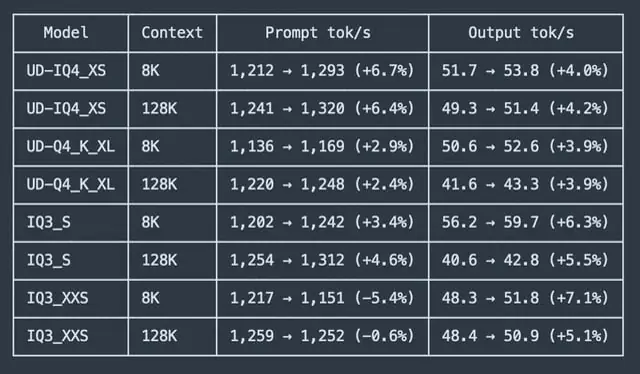
The Strata author announced experimental Linux support for AMD Strix Halo with the best numbers on long-context decode and prompt processing using Unsloth Q4 and GSQ-RCO weights.
u/NoFee9147
@NoFee9147 · Oct 6
Describes async input uploads and other ROCm and llama-server fixes written with Claude that sped up Flash-Next decode on a Lenovo P620 with four 7900 XTX. Offers to publish configs for other Radeon owners.
u/Yaniss916
@Yaniss916 · Oct 5
The team released 95GB EXL3 weights and a new version of their ExLlamaV3-based Kyojin engine, using speculative decoding for about 1,400 tok/s prefill.
u/EmPips
@EmPips · Oct 3
Reports an IQ3_XXS run on a 24GB Radeon and slow DDR4 that beat llama.cpp's 22 tok/s on the same rig. Evidence that cheap RAM can be enough.
u/pubudeux
@pubudeux · Sep 29
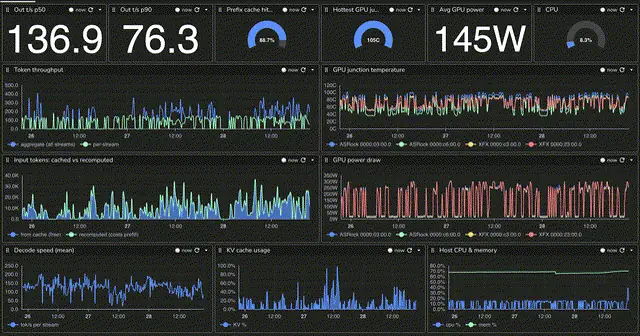
Shares a metrics dashboard from agentic coding runs on 4x R9700 using an MXFP4 quant, saying speed and quality exceeded his expectations.

u/peonist-ai
@peonist-ai · Sep 19
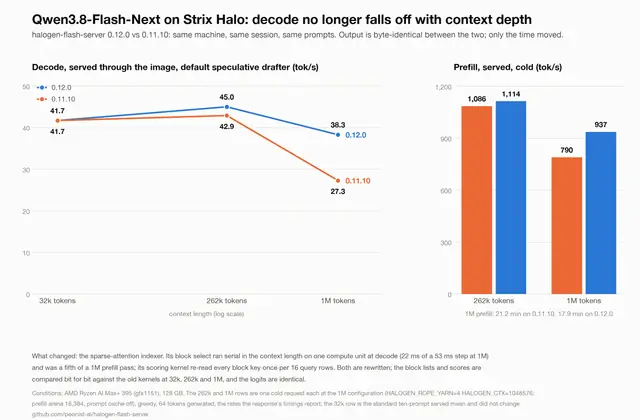
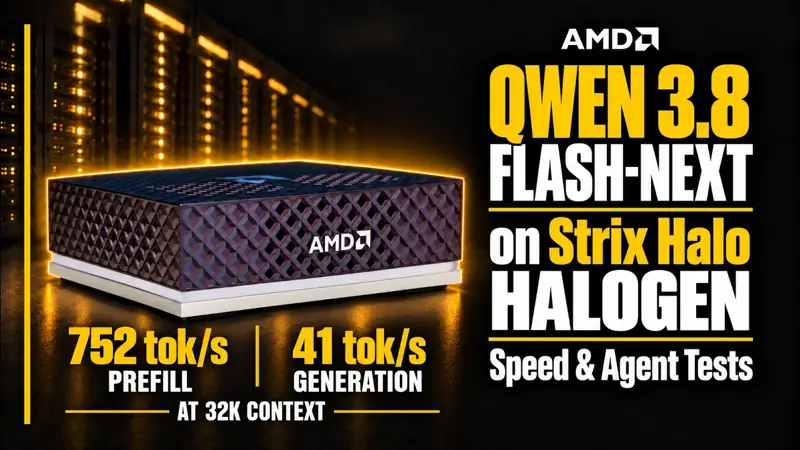
The Halogen engine author fixed slowdowns at deep context, raising decode at a million tokens from 27 to 38 tok/s on the same machine.