carloslfu
@carloslfu · Aug 28
Streams expert weights from SSD so a Mac that cannot hold the model in memory still runs it at roughly 12 tok/s. A neat trick for memory-poor Apple machines.
Alibaba Cloud· Released Aug 26
carloslfu
@carloslfu · Aug 28
Streams expert weights from SSD so a Mac that cannot hold the model in memory still runs it at roughly 12 tok/s. A neat trick for memory-poor Apple machines.

True2456
@True2456 · Sep 14
An experiment that pushes the Qwen3.8 models onto the Neural Engine of Apple Silicon rather than the GPU. A long-shot attempt to cut power use for local inference.

sethforprivacy
@sethforprivacy · Sep 27
OMLX setup using prompt-lookup MTP drafts that speed edit turns by 1.3 to 2.2x with exact output. By a privacy educator who wants coding models that stay on his own machine.

fabiogreter
@fabiogreter · Sep 11
Extends Perplexity's open Lily inference engine so it can run Qwen3.8-Flash-Next on M5 Macs. Shows how a community member adopted a corporate engine for the new model.

humanrouter
@humanrouter · Sep 4
A reproducible recipe with attributed oMLX and MLX patches, setup scripts and raw benchmarks for the 6-bit quant on an M3 Ultra. Written by an Austin AI consultant for people running big models on Macs.

MeldlabsAI
@MeldlabsAI · Oct 5
MeldLabs' release that runs Flash-Next on Apple silicon laptops at about 45 tokens per second, with a demo video.

Tomohisa Takaoka
@tomohisa · Aug 27
Screen recording of the model reading a CLI guide and completing a task that the 27B failed.

1architect
@1architect · Aug 28
A runtime focused on Qwen models that squeezes Flash-Next onto 16GB Macs. From the developer of the MacBat app.
u/DankpawsDev
@DankpawsDev · Oct 6
Made a custom MLX quant sized for a 96GB machine after finding existing models lacked the right balance of speed and headroom.
u/surrealerthansurreal
@surrealerthansurreal · Oct 6
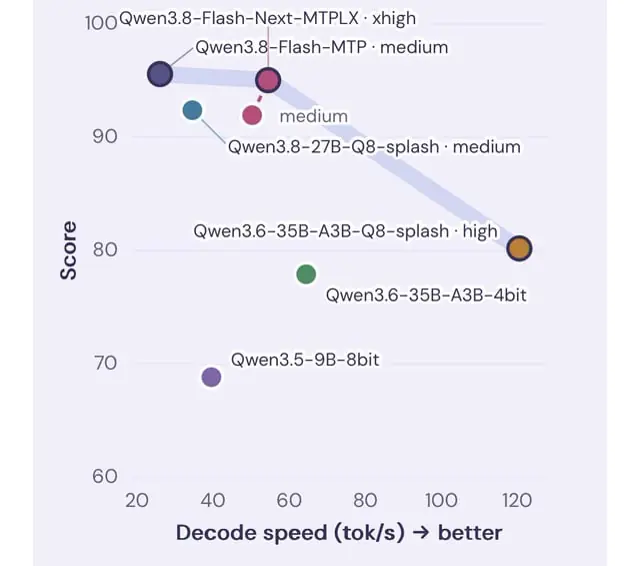
Compared Flash-Next, DeepSeek V4 Flash, GLM-5.3-Flash and other Qwen models using a private benchmark built from real coding, agentic and game tasks.
u/turtleninja99
@turtleninja99 · Oct 5
Got 17.5 tok/s decode and 360 tok/s prefill using a carousel buffer for experts and a second external SSD for parallel reads, both new tricks.