Niko1221
@Niko1221 · Sep 24
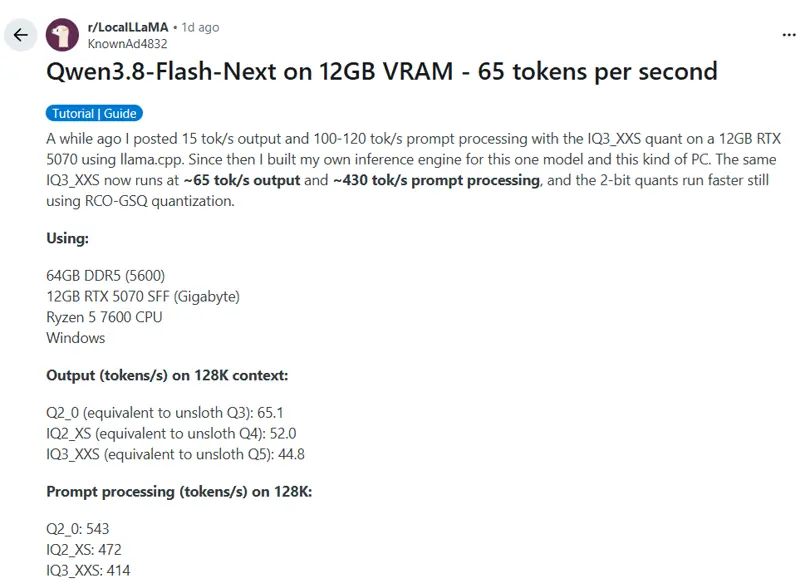
Open-source inference engine with an OpenAI/Anthropic-style local API that fits the 125B MoE onto a 12GB consumer GPU plus system RAM. The project behind the model's local-running surge.
Alibaba Cloud· Released Aug 26
Niko1221
@Niko1221 · Sep 24
Open-source inference engine with an OpenAI/Anthropic-style local API that fits the 125B MoE onto a 12GB consumer GPU plus system RAM. The project behind the model's local-running surge.

David Hendrickson
@TeksEdge · Sep 26
Tells the story of the 12GB RTX 5070 user who wrote Strata after finding llama.cpp too slow.

Alok
@analogalok · Aug 26
Posts a video of the 125B MoE running at about 21 tok/s decode with a quarter-million-token window on one gaming card, no quantised cache.

Unsloth AI
@UnslothAI · Aug 26
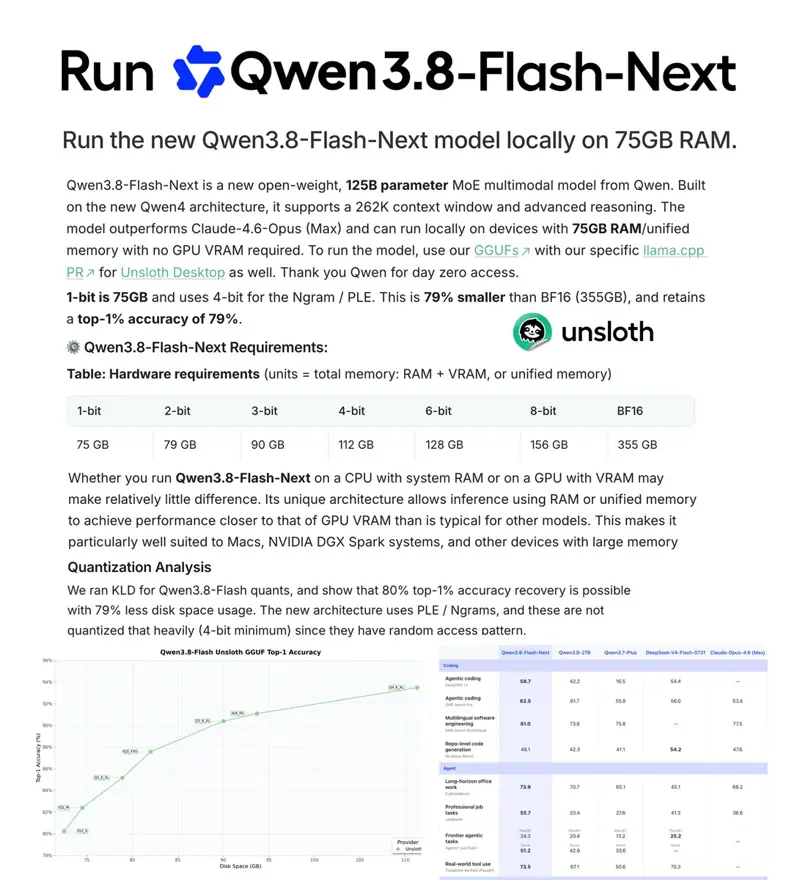
Launch-day announcement of GGUF quants and a guide for CPU and unified-memory setups.

JakeATX
@JakeATX · Sep 7
A llama.cpp variant optimised for Ampere cards, reporting very high token rates on 3090 and 3090 Ti, relevant for Flash-Next hosts.
u/Critical-Entry3377
@Critical-Entry3377 · Oct 7
Investigated why Strata 0.1.40.1 left VRAM free on a 5060 Ti, 3090 and two 3060s running Flash-Next IQ3 at 262k context, and found it was by design. A useful look at how the engine sizes its caches.
Hugging Face Forums
discuss.huggingface.co · Oct 6
Show-and-tell post for a fork with CPU decode optimisations.
u/Distinct-Pie2389
@Distinct-Pie2389 · Oct 4
A 64MB resource dashboard with rich logs that collects metrics across multiple inference engines on the network, better than the default API stats.