Flash-Next in MLX-serve with 1M context on an M5 Max 128GB
BeamstersSep 9
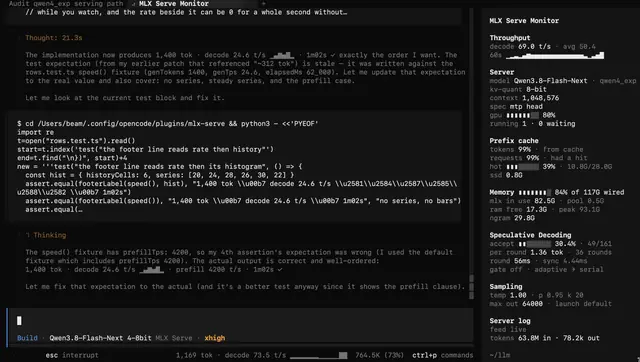
A co-creator of the MLX-serve engine support shows Flash-Next staying coherent at about 760k tokens of context with an 8-bit KV cache, demonstrated in a video.
- Launch
- Qwen3.8-Flash-Next
- Use case
- Apple silicon
- Format
- Build
- Source
- reddit.com
Beamsters