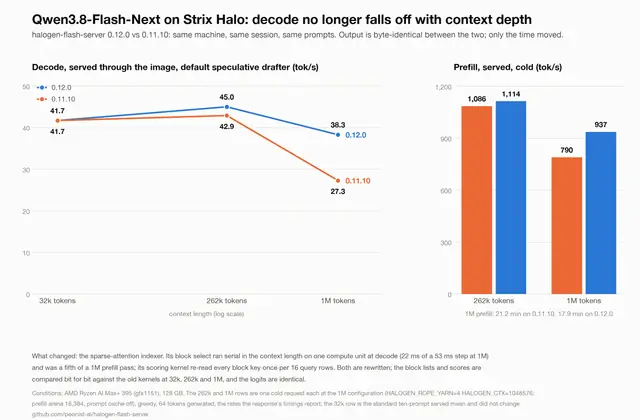
Halogen 0.12.0: Flash-Next at 1M context on Strix Halo, 38 tok/s decode
 peonist-aiSep 19
The Halogen engine author fixed slowdowns at deep context, raising decode at a million tokens from 27 to 38 tok/s on the same machine.
- Launch
- Qwen3.8-Flash-Next
- Use case
- Amd local
- Format
- Build
- Source
- reddit.com
peonist-ai