
azampatti
@azampatti · Sep 8
Quantisation and launch recipe focused purely on decode speed at 4-bit.
139 builds across 1 launch, from 131 builders.

sybil-solutions
@sybil-solutions · Oct 6
Intel GPU route with experts streamed from NVMe and 32GB host RAM.

fulvian
@fulvian · Sep 5
Experiment that edits the model's n-gram embedding table to inject removable facts without fine-tuning.

Apolog1ze-Dev
@Apolog1ze-Dev · Sep 5
A bespoke inference engine for the Qwen4-style architecture that runs Flash-Next on a 16GB card.

iIIusi0n
@iIIusi0n · Sep 19
VLLM patch and guide for running Flash-Next on a CMP 170HX with streamed embeddings.

alphastorm
@alphastorm · Aug 27
Restart-resumable local agent stack that runs Qwen3.8 on one RTX 3090/4090/5090.

Mia
@MiaAI_lab · Sep 9
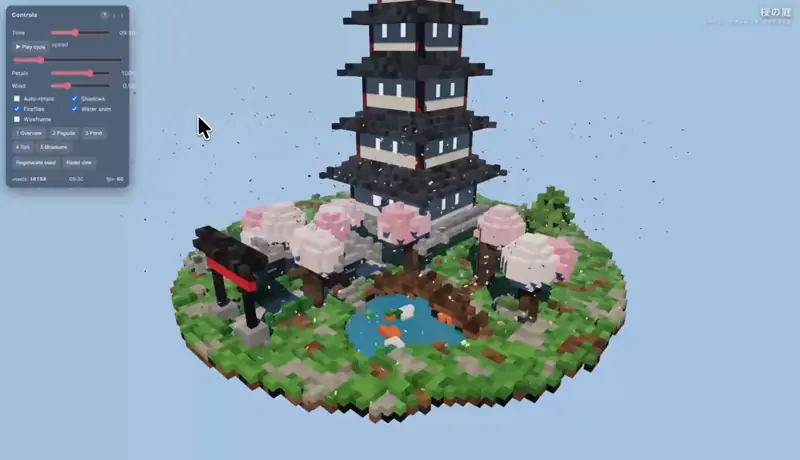
Video of a generated web scene compared against a rival model, with a live demo link.
azampatti
@azampatti · Aug 30
Convenience script that boots the model on a single DGX Spark or variant.

nguyenthimy2022kg-alt
@nguyenthimy2022kg-alt · Sep 8
Community vLLM build that runs the model on cheap ex-mining SM80 hardware.

polyuij42-del
@polyuij42-del · Sep 16
Cheap dual-card build that also scales to 800 tok/s at 23 concurrent users.

gabrielolympie
@gabrielolympie · Aug 31
SGLang patches and launchers delivering very high single-card throughput on a workstation GPU.

shawnshekari
@shawnshekari · Oct 4
An LLM engine written from scratch in HIP for AMD Strix Halo and Qwen3.8-Flash-Next, reaching about 50 tokens per second out. Built to see how far a single-model engine can go.

Aristo94
@Aristo94 · Oct 2
A llama.cpp fork that speeds ROCm prefill and fits multi-token prediction for GSQ quantizations on AMD gfx1151 hardware.

lna-lab
@lna-lab · Sep 1
Measured run using 6.6GiB of VRAM and about 48GiB of RAM on a laptop-class card.