beamnxw
@beamnxw · Sep 30
Working paper treating always-on personal agents as a new operating primitive and comparing Dots with Grok Bot.
61 entries across 11 products
Benchmarks, write-ups and discussions. 61 entries for research & posts from 55 creators on X, GitHub and Web, published Aug 11 to Oct 7.
beamnxw
@beamnxw · Sep 30
Working paper treating always-on personal agents as a new operating primitive and comparing Dots with Grok Bot.
Elliot Chen
@ElliotChen · Aug 13
Short video tip for first-time users plus a note on opt-in tools that let the agent extend itself.

nihaldipak650-collab
@nihaldipak650-collab · Oct 6
Evidence log of orchestrating Codex, a dot and Muse together, with failure cases and progress-checking methods.

storminator89
@storminator89 · Oct 2
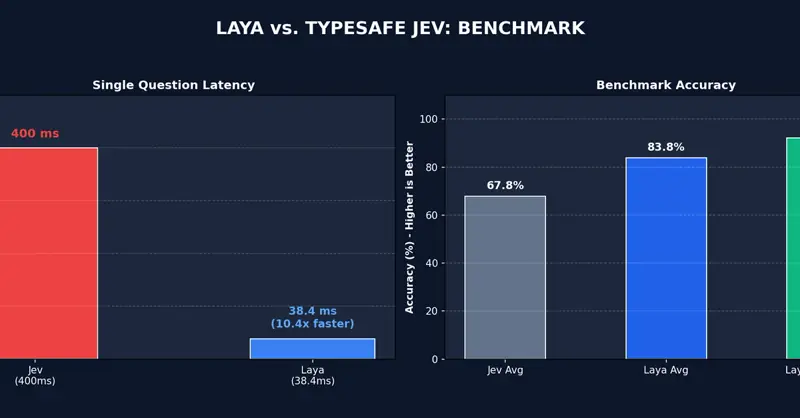
A German-language benchmark comparing Cloudflare Clef Flash 9B, Jev and a 4B model, with test inputs, reference labels, native outputs and evaluation.

shiiiIIiIiiin
@shiiiIIiIiiin · Oct 7
Short proofs for six Graffiti conjectures (198, 219, 252, 254, 584 and 712) written with Opus 5.5 and GPT-6.1 Sol.

greenlitlabs
@greenlitlabs · Oct 5
Code for a Portuguese article comparing Clef against two generative LLMs on 24 hand-labelled support tickets, using the probability as a certainty threshold for automation.

ganson-labs
@ganson-labs · Oct 4
Tournament where teams of agents built from Claude Sonnet 5.5 and GPT-6.1 Sol each write a territory-capture entry, to compare the models head to head.

PrabhudevG2
@PrabhudevG2 · Oct 2
Four jobs with three attempts each for Claude Sonnet 5.5 and GPT-6.1 Sol, with briefs, checks and every attempt published for replication.

joonlab
@joonlab · Sep 30
Dataset and scorecard from 3,527 calls across seven tracks comparing Sol 6.1 with GPT-6 Sol, Astra, Luna and GPT-5.6 Sol, with per-item results.