upendrasingh1
@upendrasingh1 · Oct 6
Fine-tunes Clef decision models on a 12 GB GPU for real-time entity resolution with TRL comparisons.
175 entries for this week from 169 creators on GitHub, YouTube and Reddit, published Oct 5 to Oct 8.
upendrasingh1
@upendrasingh1 · Oct 6
Fine-tunes Clef decision models on a 12 GB GPU for real-time entity resolution with TRL comparisons.

kkarimi
@kkarimi · Oct 6
Reproducible fine-tune study with paired evaluation and tutorials, using a playable Tetris-like game as the task.

dchristopoulos
@dchristopoulos · Oct 6
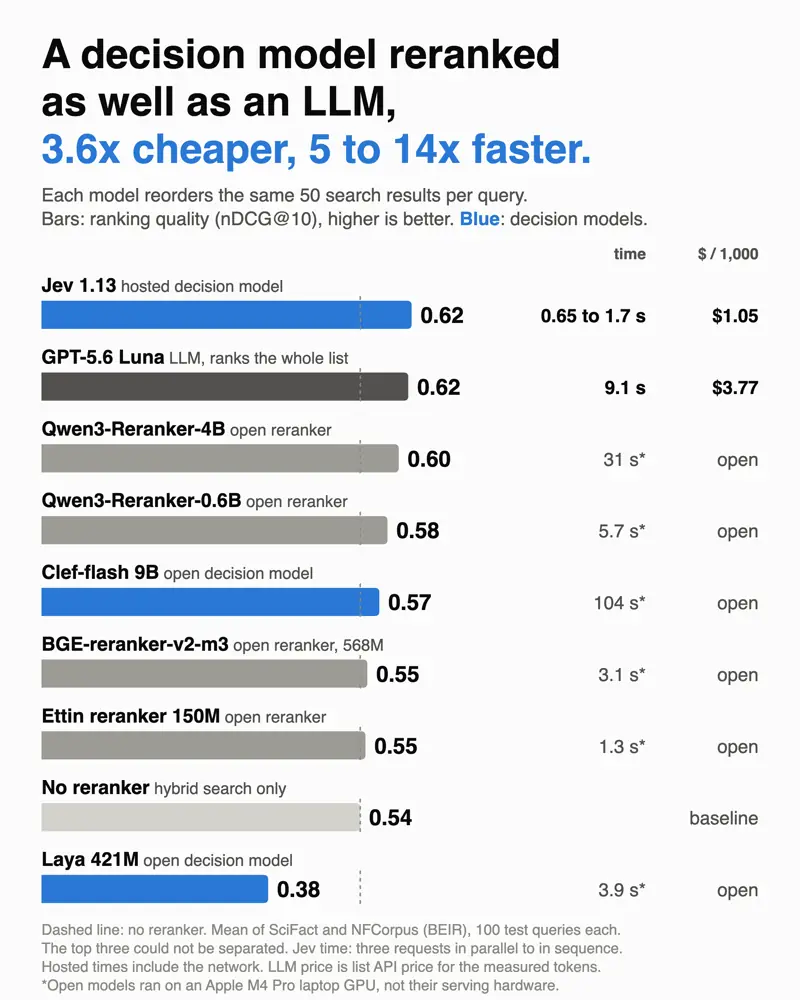
Benchmarks Jev, Clef-flash and Laya against an LLM and six rerankers on BEIR with paired confidence intervals.

Sj0605-DataSci
@Sj0605-DataSci · Oct 6
Common-ground comparison of Jev, Clef, Kev and others against embeddings, rerankers, NLI and prompted LLMs.

u9401066
@u9401066 · Oct 6
Clef-Flash reviews each reasoning step of a llama-server model and triggers rollback or reflection.

odiak
@odiak · Oct 6
A collection of Japanese demos built on Cloudflare Workers AI's Clef and Clef-flash decision models.

Gilad Fride
@giladfr · Oct 6
Gilad Fride adapted the Muse Gadget firmware to the ESP32 Cheap Yellow Display board, a very low-cost touchscreen option for Muse hardware.

moritz-prenner
@moritz-prenner · Oct 6
Moritz Prenner is designing his own ESP32 circuit board for a Muse gadget instead of using an off-the-shelf dev kit.

balanceryzh
@balanceryzh · Oct 6
Browser game created entirely by a dot, shared as a sample of what the agent can build from a prompt.

JoeyWangTW
@JoeyWangTW · Oct 6
Self-hosted voice inbox that sends Pebble Index 01 ring notes to Notion and turns tasks into work for a dot.

arjav1181
@arjav1181 · Oct 6
Colony of always-on agents running a one-person content business, offered as an open-source variant of Dots.

gbesse
@gbesse · Oct 6
Portable incwo MCP workflows for ChatGPT dots, wiring a French business suite into the agent.

Valdemar-Yu
@Valdemar-Yu · Oct 6
Claude Code skill in which Opus conducts and judges while GPT-6.1 Sol executes through the Codex CLI, with supervision every 30 minutes.

xXseesXx
@xXseesXx · Oct 6
Attempt to port the LDLib2 library to the GTNH Minecraft modpack using GPT-6.1 Sol at xhigh effort.
Hugging Face Forums
discuss.huggingface.co · Oct 6
Show-and-tell post for a fork with CPU decode optimisations.
u/NoFee9147
@NoFee9147 · Oct 6
Describes async input uploads and other ROCm and llama-server fixes written with Claude that sped up Flash-Next decode on a Lenovo P620 with four 7900 XTX. Offers to publish configs for other Radeon owners.
u/bobaburger
@bobaburger · Oct 6
Went from sceptic to convert after trying Strata on a low-end 5060 Ti with 32GB RAM and showed what the speed feels like in real demos.

u/KnownAd4832
@KnownAd4832 · Oct 6
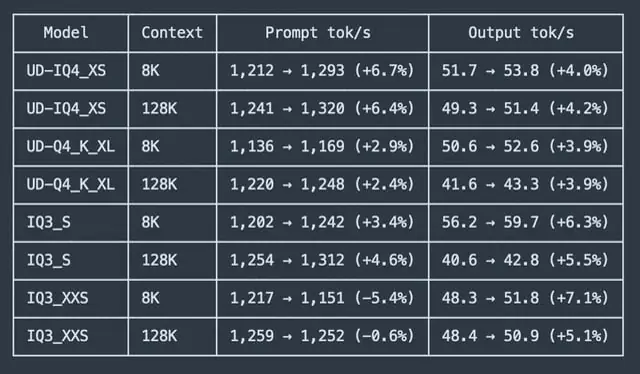
The Strata author announced experimental Linux support for AMD Strix Halo with the best numbers on long-context decode and prompt processing using Unsloth Q4 and GSQ-RCO weights.
u/surrealerthansurreal
@surrealerthansurreal · Oct 6
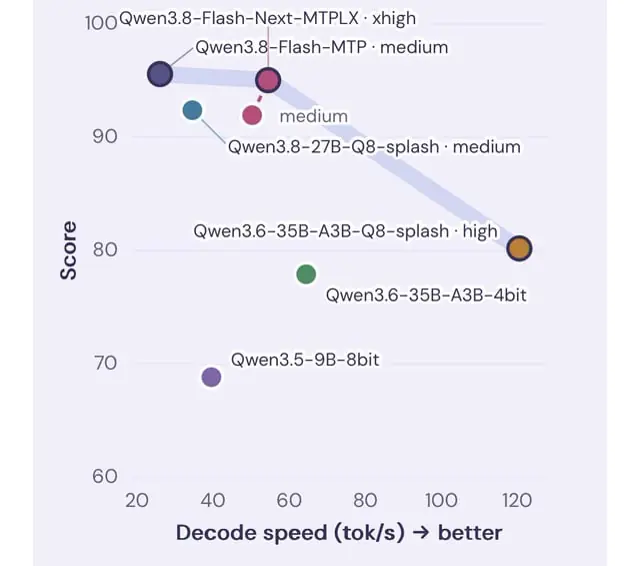
Compared Flash-Next, DeepSeek V4 Flash, GLM-5.3-Flash and other Qwen models using a private benchmark built from real coding, agentic and game tasks.
u/lkarlslund
@lkarlslund · Oct 6
A fork of the NInfer engine reaches 400 tg/s under ideal conditions with NVFP4 MoE experts on a 96GB card and the n-gram table on disk.
u/DankpawsDev
@DankpawsDev · Oct 6
Made a custom MLX quant sized for a 96GB machine after finding existing models lacked the right balance of speed and headroom.
u/deepu105
@deepu105 · Oct 6
A developer who now codes mostly locally gave both models the same complex feature in the LlamaStash Rust project and compared the results.