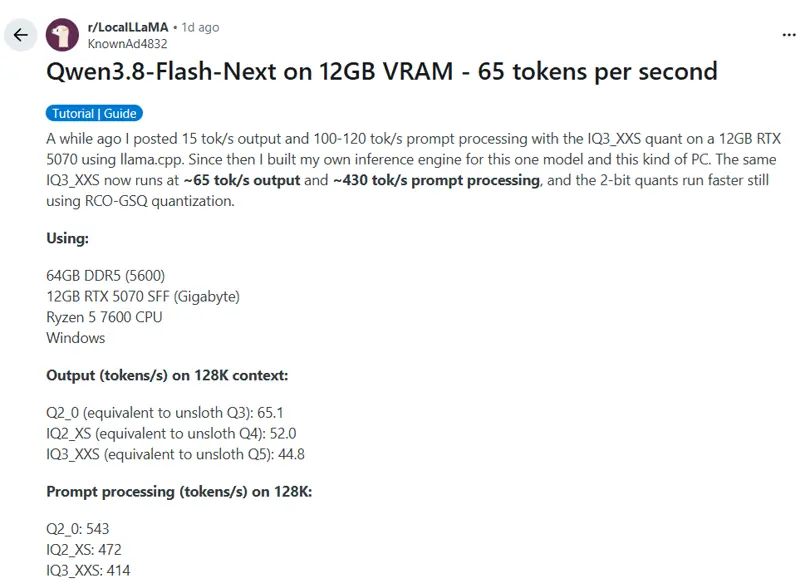
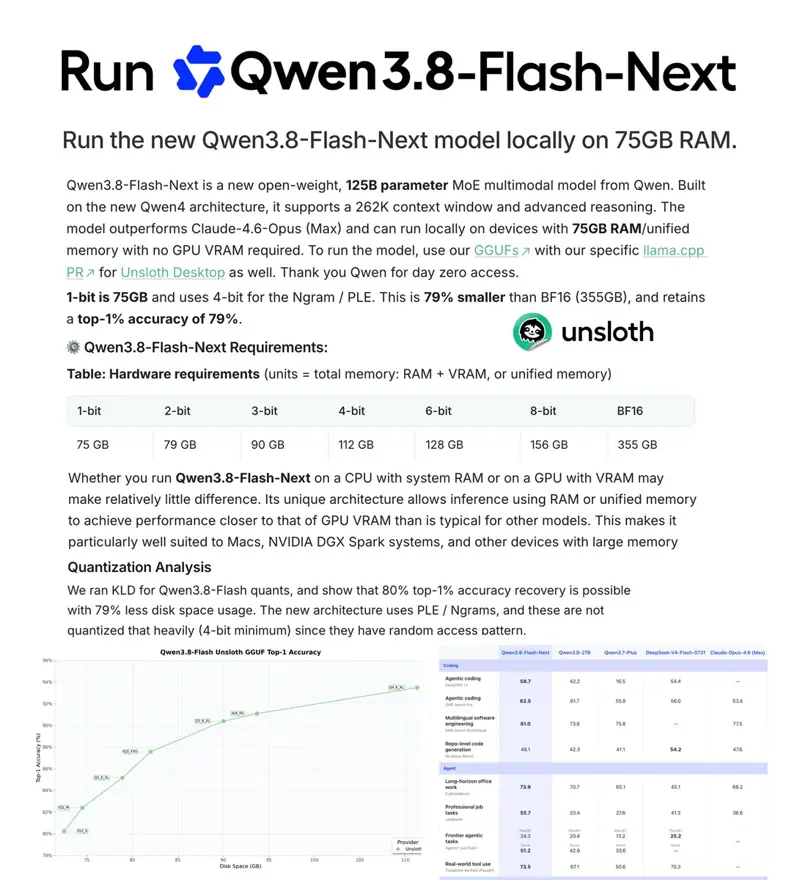
Offload most of Flash-Next's KV cache to RAM with little decode slowdown
sadnessdevilSep 16
Shows that the KV cache of qwen4exp-style models can sit in system RAM, so a quant that barely fits in VRAM can still use the full context length.
- Launch
- Qwen3.8-Flash-Next
- Use case
- Local inference
- Format
- Build
- Source
- reddit.com
sadnessdevil