Alibaba Cloud· Released Aug 26

Builds made with Qwen3.8-Flash-Next

Things people made and real use cases.

Flash-Next on a 24GB RTX 4090 with 250K contextAug 26

Entries

Alok

@analogalok · Aug 26

The VRAM barrier is officially dead.

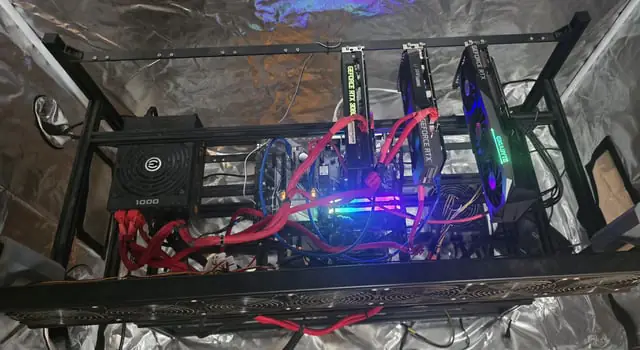
I just ran Qwen 3.8 Flash Next (MoE) 125B A6B with a 250,000 context window on a single 24GB RTX 4090.

21 tokens/sec decode. 364 t/s prefill.

no mtp. no dflash. no kv cache quantization!

We are running datacenter models on consumer…

Mia

@MiaAI_lab · Sep 9

Here's Qwen3.8-Flash with the same prompt.

It looks good, but it didn't do any firm grain, and misses many of the cool effects GLM 5.3 Flash added.

Live demo:

Tomohisa Takaoka

@tomohisa · Aug 27

MacBook Pro M4 Max 128GBで、Qwen3.8 Flash Next動きました。LMStudioからは動かなかったので、llama.cppをの対応ブランチをローカルビルドしました。Qwen3.8 27Bでは終わらなかった、まずintent-cliのガイドを読みルールを把握するタスクを完了することができました。