Alibaba Cloud· Released Aug 26

Videos made with Qwen3.8-Flash-Next

Demos, walkthroughs and reviews.

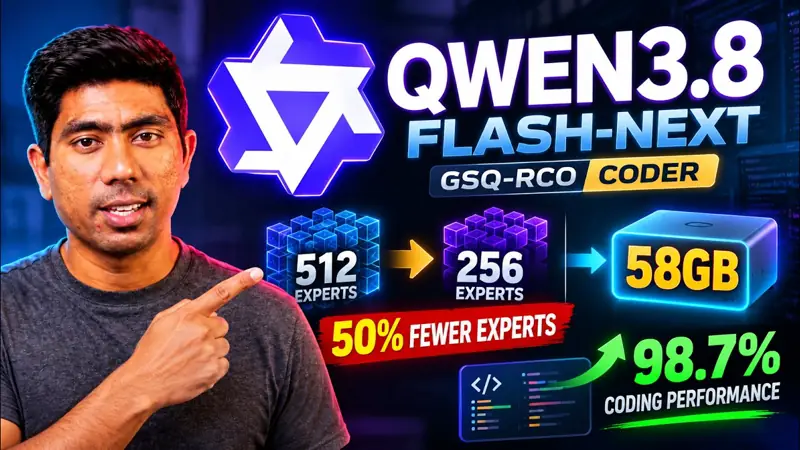
Shrinking Flash-Next to 58GB by pruning half the expertsOct 1

Entries

Execute Automation

youtube.com · Oct 1

Qwen3.8-Flash-Next is a massive Mixture-of-Experts model, but this new GSQ-RCO Coder variant from ISTA-DASLab takes a very different approach to compression.

Instead of simply quantizing everything and hoping for the best, the model uses RCO — Riemannian Constrained…
Donato Capitella

youtube.com · Sep 11

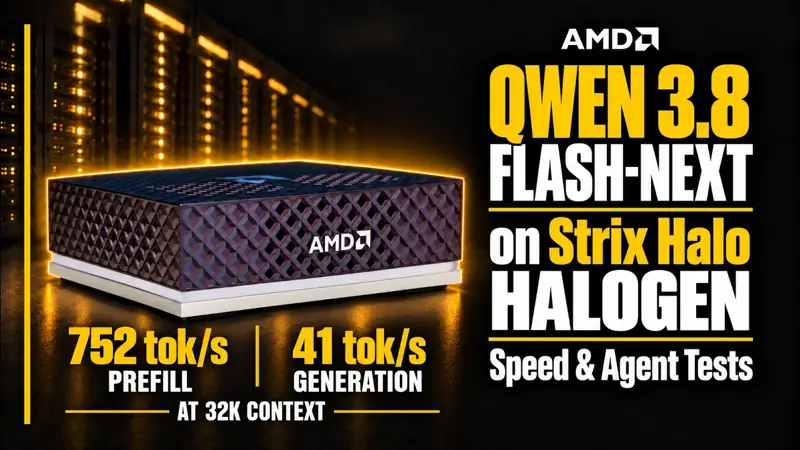
#AMD_Partner. This video is sponsored by AMD.

Qwen3.8-Flash-Next on AMD Strix Halo with 128GB RAM: how its learned N-gram embeddings work, and how Halogen Flash Server, EngramHalo and ROCm/Vulkan llama.cpp configurations compare in local inference tests.

The video covers…