slee-persis
@slee-persis · Aug 26
GVS5H: Five Qwen3.8-27B Models Match Claude Fable 5 on LiveCodeBench Hard | Fable 5 Level Coding for a Fifth the Price - or on a Single GPU
Alibaba Cloud· Released Aug 26
Benchmarks, write-ups and discussions.
slee-persis
@slee-persis · Aug 26
GVS5H: Five Qwen3.8-27B Models Match Claude Fable 5 on LiveCodeBench Hard | Fable 5 Level Coding for a Fifth the Price - or on a Single GPU

David Hendrickson
@TeksEdge · Sep 26
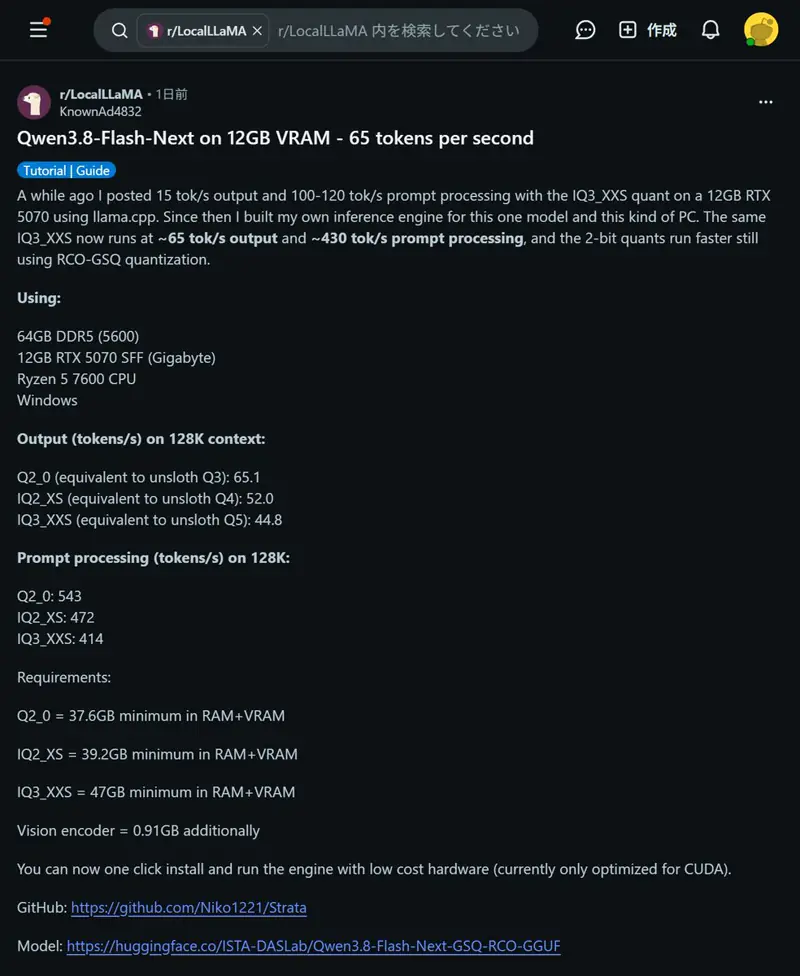
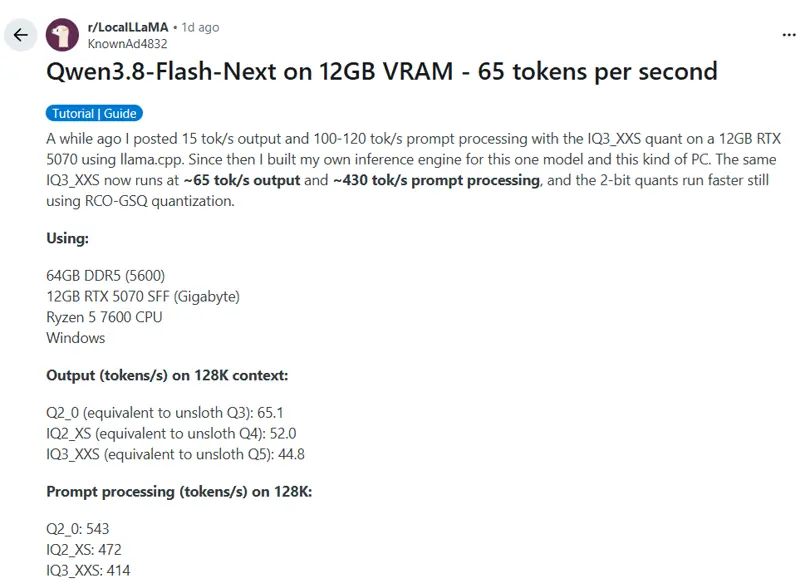
This guy was getting ~15 tps running Qwen3.8-Flash-Next on his 12GB RTX 5070.
Apparently that wasn't good enough. 😂
So he built his own inference engine. (as we all should)
Now he's reporting
🐌 llama.cpp → ~15 tps
🚀 Strata → up to 65.1 tps
And this isn't big workstation…

0xSero
@0xSero · Sep 29
GPU poor rejoice!
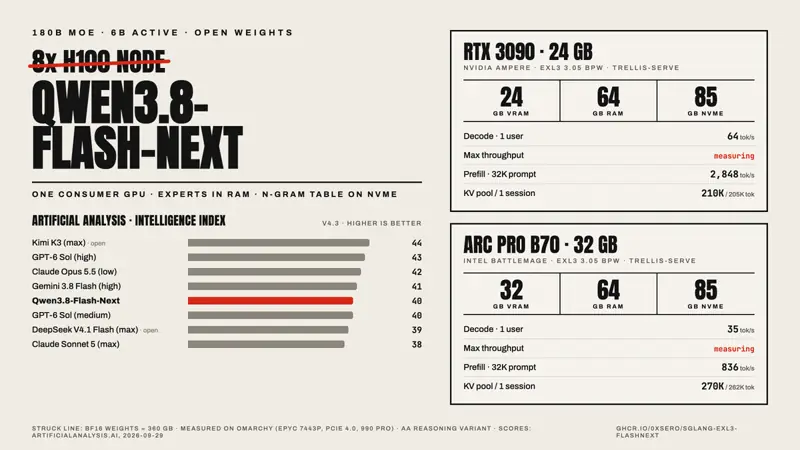
You will be able to run Qwen3.8-Next-Flash on a single 24-32 GB GPU + 64GB ddr4/ddr5 + 100GB NVMe/SSD
RTX 3090:
Intel Arc B70:

Unsloth AI
@UnslothAI · Aug 26
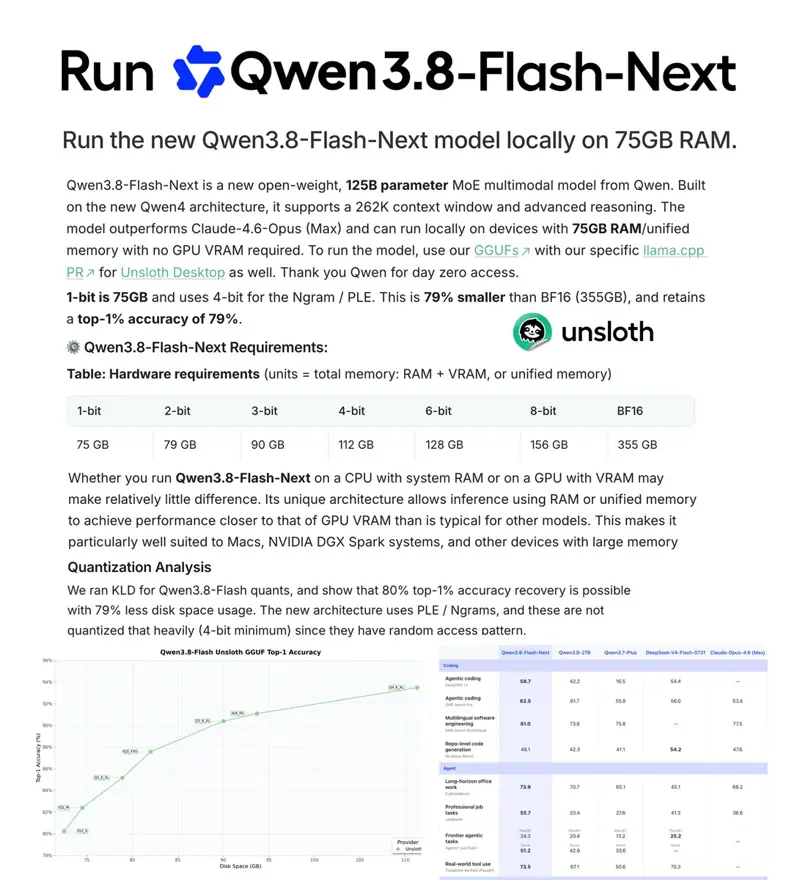
Qwen3.8-Flash can now be run locally! 🔥
The 125B MoE model outperforms Claude-Opus-4.6 (Max).
Run on 75GB RAM via Unsloth GGUFs.
Qwen3.8-Flash-Next enables CPU RAM / unified mem setups to deliver near VRAM speeds.
Guide: https://t.co/LLMclyJTeL
GGUF:

ハカセ アイ
@ai_hakase_ · Sep 26
【Qwen3.8-Flash-Nextを12GB VRAMで激速化する「Strata」】
👉 https://t.co/H6Cz6pixg0
12GB VRAMの限定された環境でも、カスタム推論エンジン「Strata」と高度な非一様量子化を使うことで、Qwen3.8-Flash-Nextを最高クラスの速度で動かせるそうです!なんと出力が約65 tok/sという驚異的なスピードですね!✨
遅延…