MKRWW
@MKRWW · Aug 27
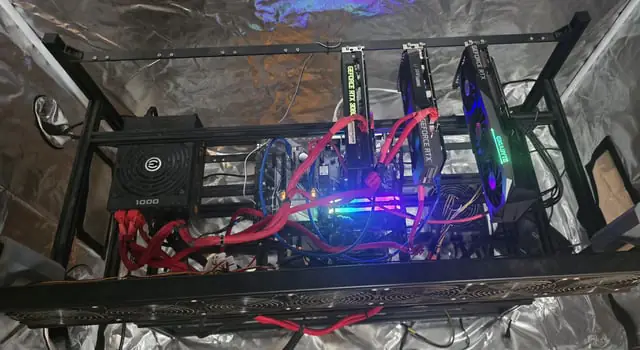
German-language write-up of benchmark numbers, test harness and results for running the model on three second-hand 3090s.
Alibaba Cloud· Released Aug 26
Open-weight 125B-parameter multimodal MoE (about 6B active, plus a 51B n-gram embedding table) from Alibaba's Qwen team, an early preview of the Qwen4 architecture. Its n-gram table can sit in system RAM or on SSD, which let community engines such as Strata run it on gaming PCs and Macs.
MKRWW
@MKRWW · Aug 27
German-language write-up of benchmark numbers, test harness and results for running the model on three second-hand 3090s.

1architect
@1architect · Aug 28
A runtime focused on Qwen models that squeezes Flash-Next onto 16GB Macs. From the developer of the MacBat app.
u/Tight_Commercial7
@Tight_Commercial7 · Oct 7
Gave the same simple prompt for a widget-rich Android weather app to Flash-Next and other Qwen models to see which produced a working app.
u/Critical-Entry3377
@Critical-Entry3377 · Oct 7
Investigated why Strata 0.1.40.1 left VRAM free on a 5060 Ti, 3090 and two 3060s running Flash-Next IQ3 at 262k context, and found it was by design. A useful look at how the engine sizes its caches.

u/flynth92
@flynth92 · Oct 7
Posted a llama.cpp multi-GPU fork with binaries and Docker images after running five 262k-token sessions on six PCIe-only cards. Shows big-MoE long-context serving is possible on plain consumer rigs.
u/deepu105
@deepu105 · Oct 6
A developer who now codes mostly locally gave both models the same complex feature in the LlamaStash Rust project and compared the results.
u/DankpawsDev
@DankpawsDev · Oct 6
Made a custom MLX quant sized for a 96GB machine after finding existing models lacked the right balance of speed and headroom.
u/lkarlslund
@lkarlslund · Oct 6
A fork of the NInfer engine reaches 400 tg/s under ideal conditions with NVFP4 MoE experts on a 96GB card and the n-gram table on disk.
u/surrealerthansurreal
@surrealerthansurreal · Oct 6
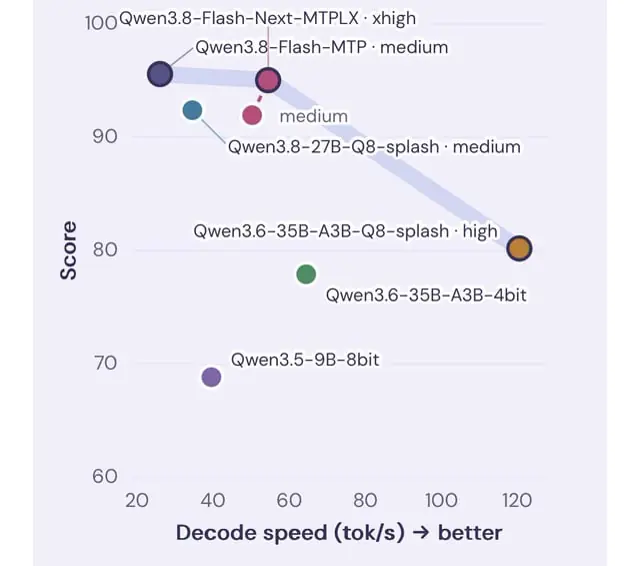
Compared Flash-Next, DeepSeek V4 Flash, GLM-5.3-Flash and other Qwen models using a private benchmark built from real coding, agentic and game tasks.

u/KnownAd4832
@KnownAd4832 · Oct 6
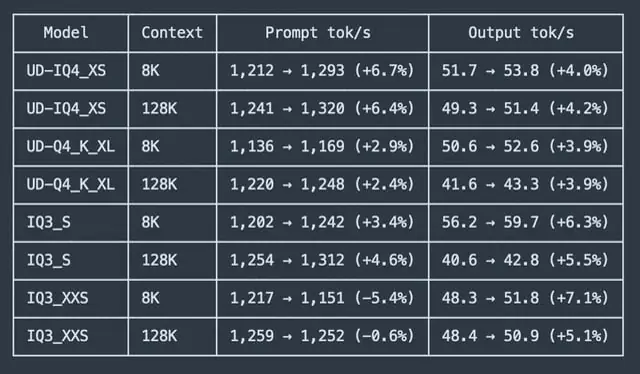
The Strata author announced experimental Linux support for AMD Strix Halo with the best numbers on long-context decode and prompt processing using Unsloth Q4 and GSQ-RCO weights.
u/bobaburger
@bobaburger · Oct 6
Went from sceptic to convert after trying Strata on a low-end 5060 Ti with 32GB RAM and showed what the speed feels like in real demos.
u/NoFee9147
@NoFee9147 · Oct 6
Describes async input uploads and other ROCm and llama-server fixes written with Claude that sped up Flash-Next decode on a Lenovo P620 with four 7900 XTX. Offers to publish configs for other Radeon owners.
Hugging Face Forums
discuss.huggingface.co · Oct 6
Show-and-tell post for a fork with CPU decode optimisations.
u/MushroomMan234
@MushroomMan234 · Oct 5
Showed that UkisAI's reasoning-efficient fine-tune finishes agent tasks at xhigh effort sooner than base Flash-Next at medium, using a Rust/CUDA engine for GB10.

u/sdfprwggv
@sdfprwggv · Oct 5
Posted full flags for an NVFP4 Strata fork with FP8 PLE, INT8 KV cache and MTP on a single 32GB Blackwell card with 64GB DDR5.
u/Yaniss916
@Yaniss916 · Oct 5
The team released 95GB EXL3 weights and a new version of their ExLlamaV3-based Kyojin engine, using speculative decoding for about 1,400 tok/s prefill.
u/turtleninja99
@turtleninja99 · Oct 5
Got 17.5 tok/s decode and 360 tok/s prefill using a carousel buffer for experts and a second external SSD for parallel reads, both new tricks.
u/Distinct-Pie2389
@Distinct-Pie2389 · Oct 4
A 64MB resource dashboard with rich logs that collects metrics across multiple inference engines on the network, better than the default API stats.
u/Chida82
@Chida82 · Oct 4
Forked the DwarfStar engine, removed everything except Qwen3.8 Flash Next and ported extra optimizations for Mac, with a few upstream PRs in the queue.
u/Shot-Ad-4147
@Shot-Ad-4147 · Oct 4
Tested four ways of placing Strata's n-gram table on a 4090 48GB with 128GB RAM and found the default is right while parking conversations is what really helps.
u/okoyl3
@okoyl3 · Oct 4
Forked Strata with Opus 5.5 to run Flash-Next on a 2018 POWER9 machine with V100 GPUs over NVLink, hitting 113 tok/s decode.
u/Short_Regular_7191
@Short_Regular_7191 · Oct 3
Ran two local models against Opus 4.6 on the same tasks to see how much real coding work can stay local, and reports that one of them tied. Posted as numbers, not a fight.