ruashots
@ruashots · Aug 27
A homelab owner's practical write-up and configs.
Alibaba Cloud· Released Aug 26
Open-weight 125B-parameter multimodal MoE (about 6B active, plus a 51B n-gram embedding table) from Alibaba's Qwen team, an early preview of the Qwen4 architecture. Its n-gram table can sit in system RAM or on SSD, which let community engines such as Strata run it on gaming PCs and Macs.

MeldlabsAI
@MeldlabsAI · Oct 5
MeldLabs' release that runs Flash-Next on Apple silicon laptops at about 45 tokens per second, with a demo video.

deathbyorderfill
@deathbyorderfill · Aug 26
Compresses the embedding table so a single Spark holds the whole thing at long context.

vcruz305
@vcruz305 · Sep 17
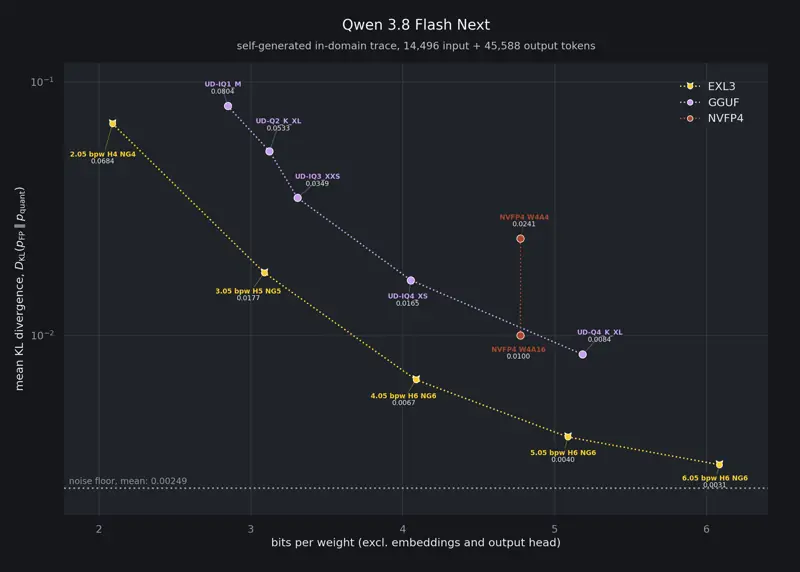
Ports ExLlamaV3 kernels to RDNA 3.5 with grouped MoE, int8 mixers and MTP. The author quantizes frontier models down to fit smaller GPUs.

drluoto
@drluoto · Aug 29
Draft-head speculation and carefully measured Vulkan settings that lift Flash-Next speed on Strix Halo. Notable for publishing the measurement method as well as the numbers.

abliter8-ai
@abliter8-ai · Aug 28
A step-by-step serving recipe for running the 125B MoE on one Ryzen AI MAX+ 395 box, written by a hobbyist. Useful as a replicable baseline for that hardware.

olliehm
@olliehm · Sep 10
Build recipe, Lemonade deployment, an admission shim and benchmarks for Windows users, a platform most community recipes skip.

Bowen-Man
@Bowen-Man · Sep 7
Guide to running the EXL3 quant as a local Hermes Agent with ExLlamaV3 and native OpenAI tool calling on consumer GPUs.

Tomohisa Takaoka
@tomohisa · Aug 27
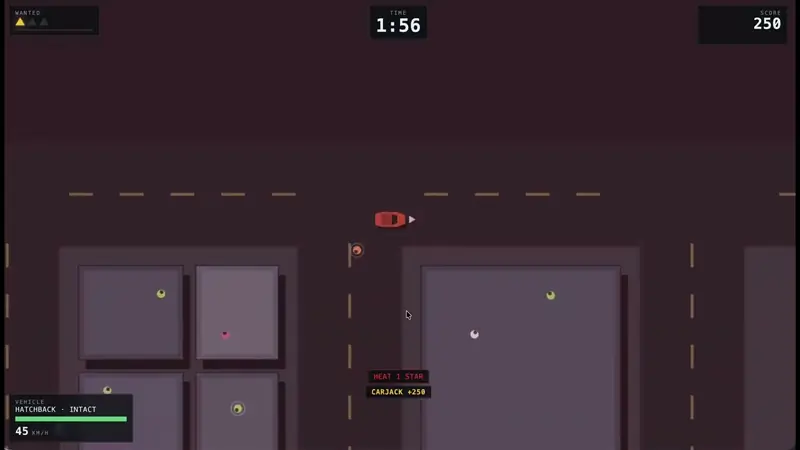
Screen recording of the model reading a CLI guide and completing a task that the 27B failed.

moriyasujapan
@moriyasujapan · Sep 21
Reaches 1M KV tokens using FP8 PLE on a 91GB host, a cheap high-throughput setup.