u/EmPips
@EmPips · Oct 3
Reports an IQ3_XXS run on a 24GB Radeon and slow DDR4 that beat llama.cpp's 22 tok/s on the same rig. Evidence that cheap RAM can be enough.
Alibaba Cloud· Released Aug 26
Open-weight 125B-parameter multimodal MoE (about 6B active, plus a 51B n-gram embedding table) from Alibaba's Qwen team, an early preview of the Qwen4 architecture. Its n-gram table can sit in system RAM or on SSD, which let community engines such as Strata run it on gaming PCs and Macs.
u/EmPips
@EmPips · Oct 3
Reports an IQ3_XXS run on a 24GB Radeon and slow DDR4 that beat llama.cpp's 22 tok/s on the same rig. Evidence that cheap RAM can be enough.
u/matteiuspi
@matteiuspi · Oct 2
Hardware notes, vLLM work and benchmarks from an unusual inference machine built around cheap Ascend cards, which are not CUDA drop-ins.
u/Fz1zz
@Fz1zz · Oct 2
Shows three Strata patches that let a 5090 plus a 4070 Ti Super on a PCIe x1 slot run the 76GB IQ3_XXS quant at 1,800 tok/s prompt processing.
Execute Automation
youtube.com · Oct 1
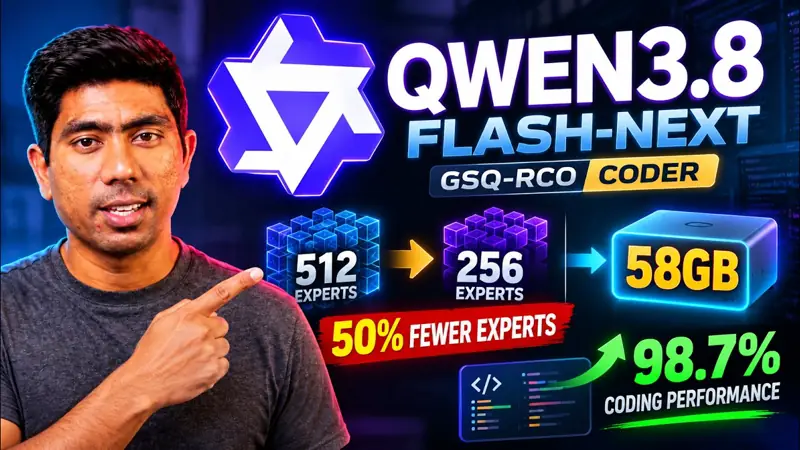
Walkthrough of a pruned build that claims about 98.7% of the coding score at much lower memory.
u/rmonsurate
@rmonsurate · Sep 30
A lab used a Dell B300 for two fine-tunes of Flash-Next, pruning experts from 512 to 288 per layer with REAP and retraining at NVFP4, GGUF included.
u/MLDataScientist
@MLDataScientist · Sep 30
Benchmarked Flash-Next on a 12GB VRAM, 64GB RAM laptop and reached 50 tok/s decode and 1500 tok/s prefill, saying other llama.cpp forks were nowhere close.
u/pubudeux
@pubudeux · Sep 29
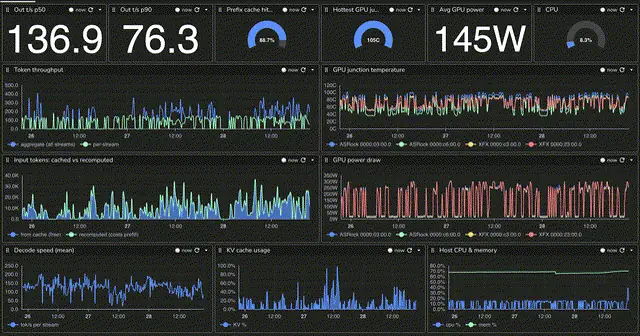
Shares a metrics dashboard from agentic coding runs on 4x R9700 using an MXFP4 quant, saying speed and quality exceeded his expectations.
u/TypicalPudding6190
@TypicalPudding6190 · Sep 27
A team built an engine that keeps most of the NVFP4 model on SSD and reads experts as tokens need them, reaching 9-10 tok/s decode on a 16GB card with 32GB RAM.
u/Nicolodeva
@Nicolodeva · Sep 25
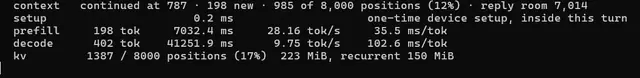
Transferred the pretrained n-gram table into a tiny Qwen model and got 5% lower validation perplexity, trained mostly on free Kaggle GPUs. A resourceful research experiment.
u/Secure_Recording_472
@Secure_Recording_472 · Sep 24
Announced by the builder at UkisAI: a Qwen-based family trained to avoid pathological overthinking, with Flash-Next and 27B variants and 350k+ downloads in 13 days.

u/KnownAd4832
@KnownAd4832 · Sep 24
Went from 15 tok/s in llama.cpp to about 65 tok/s by writing an inference engine for this one model and this class of PC, with 2-bit RCO-GSQ quants running faster still.
u/Thin_Pollution8843
@Thin_Pollution8843 · Sep 20
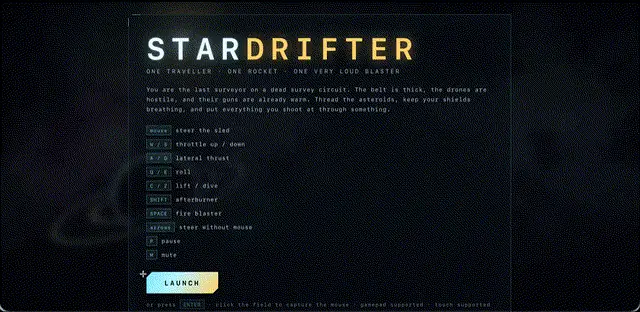
Ran Intel AutoRound W4A16 Flash-Next on four V620 cards for about three hours with an OMP harness, letting it test and fix a game itself in two browsers.

u/peonist-ai
@peonist-ai · Sep 19
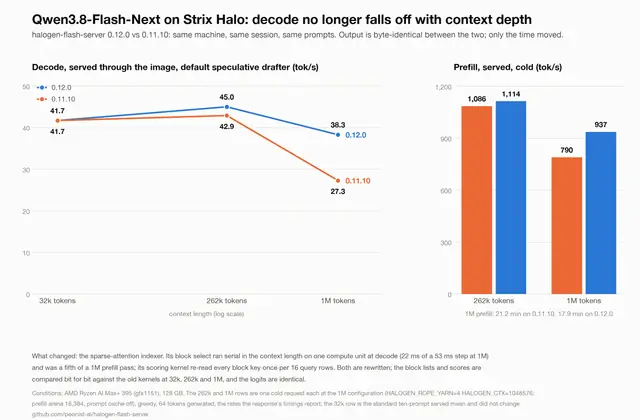
The Halogen engine author fixed slowdowns at deep context, raising decode at a million tokens from 27 to 38 tok/s on the same machine.
u/sadnessdevil
@sadnessdevil · Sep 16
Shows that the KV cache of qwen4exp-style models can sit in system RAM, so a quant that barely fits in VRAM can still use the full context length.
u/carteakey
@carteakey · Sep 14
Walks from a bare 6 tok/s up through successive patches on a middle-tier PC with Gen4 NVMe, documenting what actually helped. A guide others can follow.
pfeifferj
huggingface.co · Sep 14
Non-uniform quant repo that Strata users commonly pair with the engine.
Donato Capitella
youtube.com · Sep 11
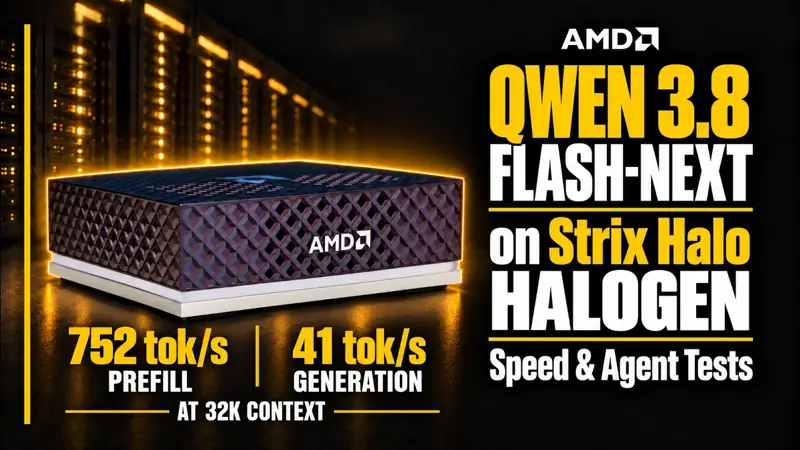
Detailed benchmark session on a Strix Halo mini PC covering the n-gram table trick.