andreasknopke
@andreasknopke · Sep 14
Qwen3.8-Flash-Next 180B MoE on one DGX Spark — stable recipe with KV-loop fixes, KDA decode kernel, EAGLE speculation.
Alibaba Cloud· Released Aug 26
Open-source code, templates and lists.
andreasknopke
@andreasknopke · Sep 14
Qwen3.8-Flash-Next 180B MoE on one DGX Spark — stable recipe with KV-loop fixes, KDA decode kernel, EAGLE speculation.

provsalt
@provsalt · Aug 27
Qwen 3.8 Flash NVFP4 with PLE NVFP4 quantized to run on a single DGX Spark

lukaLLM
@lukaLLM · Aug 31
• NEW: Qwen3.8 Flash: Over 7x Faster First Token | llama.cpp vs SGLang vs FreeToken. Benchmarked! https://youtu.be/RlsxXB5q-cA
• Why Qwen3 8 Flash Is So Cheap to Run 0 to 96GB VRAM Explained and Tested! https://youtu.be/L4XyWM6IrBc
• DeepSeek V4 Flash 284B on a single RTX 6000…

halt95
@halt95 · Sep 2
Qwen3.8-Flash-Next on 4x RTX 3090 with vLLM: 924,993 kv pool, 160-175tok/s single decode, 3 x 262K sessions resident, MTP, host-mapped PLE, pinned build and container recipes.

SSHdotCodes
@SSHdotCodes · Aug 26
SGLang 0.5.21 for Qwen3.8-Flash-Next on one RTX PRO 6000: 264.5 tok/s decode, W4A16 routed experts (KLD 0.0111 vs BF16), 262K context, exact speculative rejection sampling, reproducible benchmarks.

HaberstrohSystems
@HaberstrohSystems · Sep 3
Qwen3.8-Flash-Next (176B MoE, 6B active) at 2.5 bpw on one 24 GB GPU with 32 GB RAM: SGLang serving patch, kernels, measurement tools and engineering log

hashd1ve
@hashd1ve · Aug 26
Qwen3.8-Flash-Next on a single DGX Spark (GB10): a 126.0 GiB checkpoint served in 121.63 GiB of unified memory. Two SGLang patches, reproducible recipe, GSM8K-verified.

humanrouter
@humanrouter · Sep 4
Reproducible 6-bit Qwen3.8 Flash Next tuning for M3 Ultra: attributed oMLX/MLX patches, setup scripts and raw benchmarks.

ruashots
@ruashots · Aug 27
What I run on my inference server: Qwen3.8-Flash-Next on two RTX 3090s, and how I got here

getrefined
@getrefined · Aug 27
First vLLM deployment of Qwen3.8-Flash-Next (RadixArk NVFP4) on 2× DGX Spark (GB10/SM121) — TP2+EP, MTP speculative decode, CUDA graphs, 262K context. Includes the 3-line PLE FP8 quant-resolver patch the official day-0 image needs, launcher, benchmarks, and gotchas for…

MeldlabsAI
@MeldlabsAI · Oct 5
A 125B-parameter model, fully local, on a MacBook: Qwen3.8-Flash-Next at ~45 tok/s on Apple silicon.

loktar00
@loktar00 · Aug 29
Qwen3.8-Flash-Next on 4x RTX 3090: vLLM recipe, FP8 QSA KV reader for Ampere, benchmark receipts

deathbyorderfill
@deathbyorderfill · Aug 26
A 180B model that officially needs two DGX Sparks, running on one at full 256k context - by compressing the one part of the model no quantizer can touch.

bemlerlabs
@bemlerlabs · Aug 31
Production recipe for serving Qwen3.8-Flash-Next (180B Hybrid MoE) on a single 128GB NVIDIA DGX Spark with SGLang, NVMe PLE offloading & MTP speculative decoding.

vcruz305
@vcruz305 · Sep 17
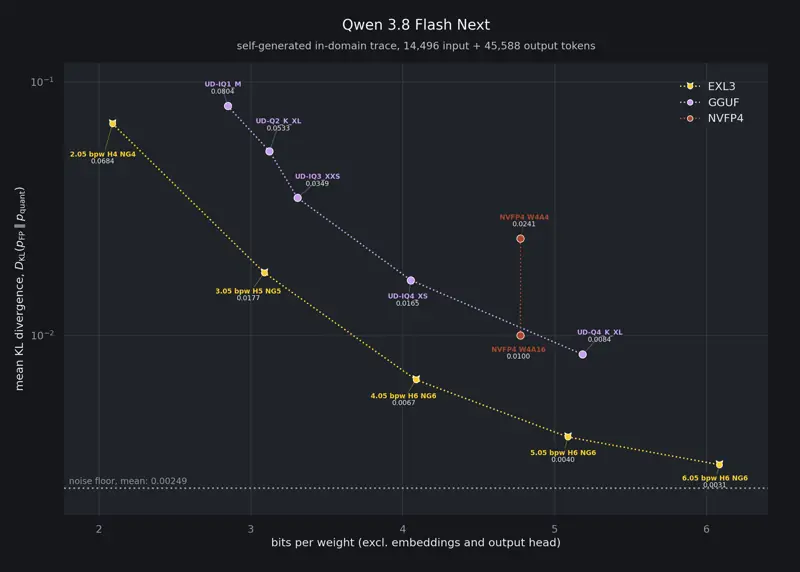
exllamav3 on AMD Strix Halo (gfx1151 / RDNA 3.5): WMMA GEMV port, grouped MoE, LDS fix, int8 mixers, MTP — 41 tok/s Qwen3.8-Flash-Next. Based on sdougbrown/exllamav3 integration.

drluoto
@drluoto · Aug 29
Vitronia — Qwen3.8-Flash-Next on AMD Strix Halo (gfx1151): 30 to 58 tok/s on Vulkan. Draft-head speculation, measurements, pitfalls, reproducible stack

abliter8-ai
@abliter8-ai · Aug 28
Serving Qwen3.8-Flash-Next on a single AMD Strix Halo (Ryzen AI MAX+ 395, gfx1151, 128 GB unified memory)

yepapa-nest
@yepapa-nest · Aug 28
Qwen3.8-Flash-Next (176B MoE) on a single RTX PRO 6000 Blackwell 96GB — NVMe-streamed PLE table, CUDA graphs with NEXTN speculation, measured against a dense 27B on the same card.

ucicelos
@ucicelos · Sep 1
Qwen3.8-Flash-Next (104 GB MoE) on a hybrid iGPU + eGPU machine: a llama.cpp tree with device-resident speculative rollback, host-cached backend hand-offs, exact sparse-attention gather, co-batched verification and long-context indexing. 22 -> 50 tok/s single-stream, 84 tok/s on…

Weschera
@Weschera · Aug 27
Qwen3.8-Flash-Next on ONE DGX Spark - 262K context, llama.cpp + unsloth GGUF

olliehm
@olliehm · Sep 10
Qwen3.8-Flash-Next on Windows / Strix Halo: build recipe, Lemonade deployment, admission shim, benchmarks